Scrapy, part 2: JavaScript, forms, and dynamic pages
· Surendra Tamang
JavaScript, forms, and dynamic pages
Part 1 dealt with sites that hand you clean HTML. This part is about the ones that do not: pages that render with JavaScript, data hidden behind a login, and content that only appears after a form or a scroll.
All the code is on GitHub: scrapy-tutorial/part-2-dynamic-pages. Same as before, the spiders point at placeholder sites so the focus stays on the technique. Swap the domain and selectors to run them for real.
First, decide how to get the data
When a page renders with JavaScript, most people jump straight to a headless browser. That is usually the slowest option. There are three routes, and I try them in this order.
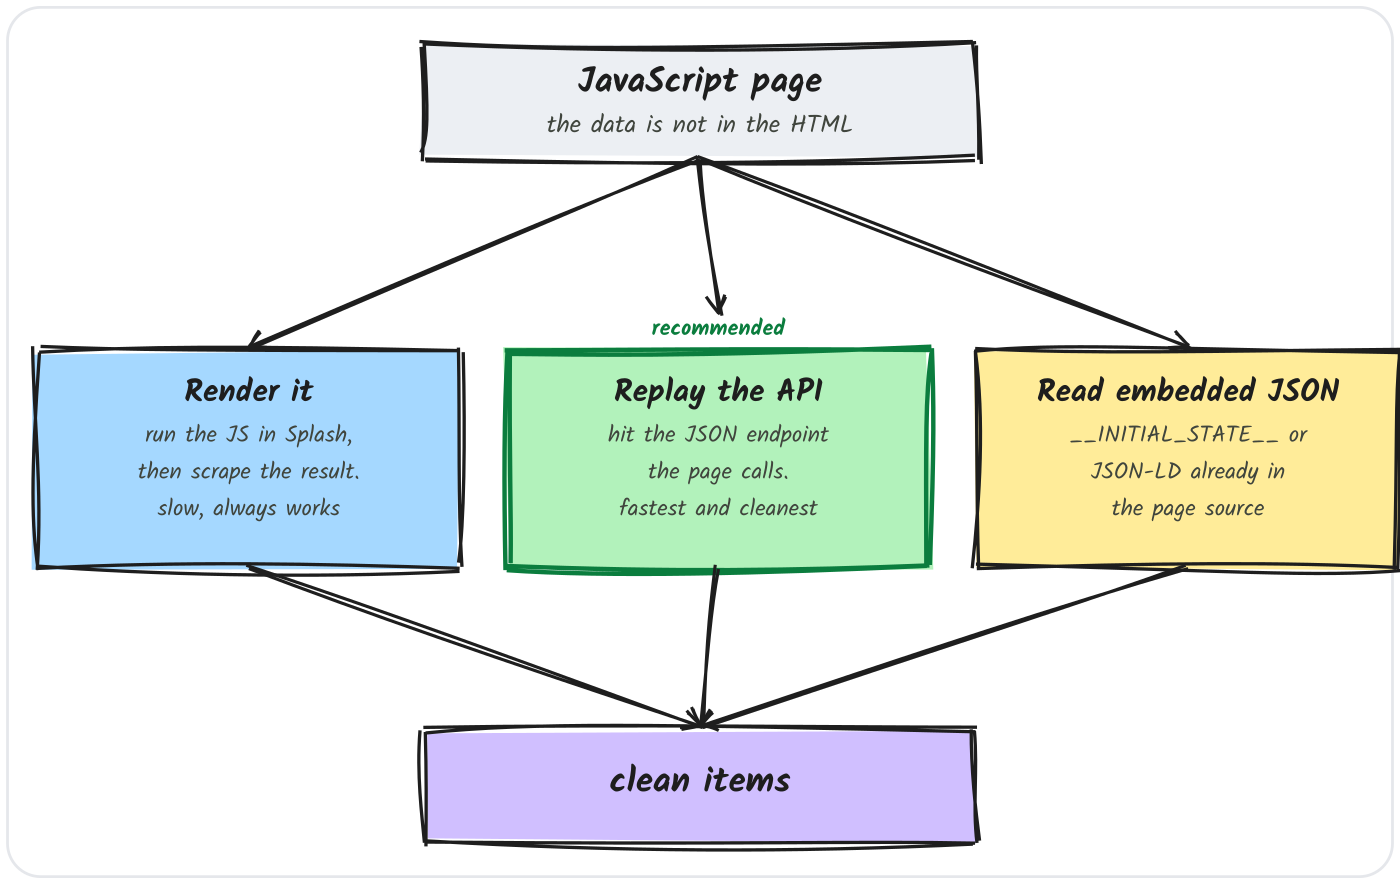
Reach for a browser last, not first. If the data arrives over an API call, hitting that endpoint is faster and far more stable than rendering the whole page. So before writing any Splash code, open the network tab and look for the request that returns the data.
Rendering with Splash
Full file: webscraper/spiders/spa_spider.py
When the data really is built in the browser, Splash runs the JavaScript for you. It takes a small Lua script that says what to do on the page: load it, wait for the content, scroll, click. You send a SplashRequest instead of a normal one.
yield SplashRequest( url=url, callback=self.parse, args={'lua_source': LUA_SOURCE, 'timeout': 30, 'wait': 5},)The Lua part is where you wait for the right element and interact with the page:
splash:go(args.url)splash:wait(3)splash:runjs("window.scrollTo(0, document.body.scrollHeight);")
local load_more = splash:select('.load-more-btn')if load_more then    load_more:click()    splash:wait(3)end
Splash needs Docker running: docker run -p 8050:8050 scrapinghub/splash. The full file has the complete Lua script and the settings block to wire it in.
Logging in and holding the session
Full file: webscraper/spiders/login_spider.py
The trick with login forms is FormRequest.from_response. It reads the existing form off the page, so hidden fields and CSRF tokens come along for free. You only add the fields you care about.
return FormRequest.from_response( response, formdata={'username': 'you', 'password': 'secret', 'csrf_token': csrf_token}, callback=self.after_login,)Scrapy keeps the session cookies after that, so the pages you visit next are already logged in. Always confirm the login actually worked before scraping, by checking for something that only shows up when signed in.
Filling a search form
Full file: webscraper/spiders/form_spider.py
Search forms are the same idea. Carry over every field the page already has, then set your own search terms on top. Copying the existing fields matters, because servers often reject a submission that is missing a hidden token they expected.
Going straight to the API
Full file: webscraper/spiders/ajax_spider.py
This is the route I reach for most. If the page loads its products from a JSON endpoint, you can skip the page and request that endpoint yourself. It returns clean structured data, no parsing of messy HTML, and it is fast.
params = {'page': page, 'limit': 20, 'format': 'json'}yield scrapy.Request( url=f'https://api-example.com/api/products?{urlencode(params)}', callback=self.parse_api_response, headers={'Accept': 'application/json', 'X-Requested-With': 'XMLHttpRequest'},)The one header that matters most is often X-Requested-With: XMLHttpRequest, since some APIs check for it. Copy the headers the real page sends and you are usually in.
Infinite scroll
Full file: webscraper/spiders/infinite_scroll_spider.py
Infinite scroll is just more of the same two options. Either drive Splash to scroll and click until the end marker appears, or find the pagination API behind the scroll and page through it directly. The second is almost always the better deal.
Middleware: rotate and retry
Full file: webscraper/middlewares.py
Middleware lets you change every request in one place. Two are worth having early: one that rotates the user agent, and one that backs off and retries when a site starts returning 429s or 503s.
def process_response(self, request, response, spider): if response.status in (429, 502, 503, 504): retries = request.meta.get('retry_times', 0) if retries < self.max_retry_times: time.sleep(self.initial_delay * (2 ** retries)) retry = request.copy() retry.meta['retry_times'] = retries + 1 retry.dont_filter = True return retry return responseThe delay doubles each attempt, so a struggling site gets room to breathe instead of a second wave of requests. The file also has proxy rotation and header rotation.
Handy selector helpers
Full file: webscraper/utils/selectors.py
A few small helpers save repetition: one that tries a list of selectors and returns the first hit, one that turns an HTML table into a list of dicts, and one that digs a JSON object out of a script tag.
What I reach for first
Check the network tab before writing a line of Splash. Nine times out of ten the data is sitting in a JSON response, and reading that is faster to write, faster to run, and far less likely to break. Save the headless browser for the sites that genuinely build their content in the page and expose no API.
What is next
Part 3 is where sites start fighting back: anti-detection, distributed crawls with Scrapy-Redis, and the monitoring you need once a crawl runs across many machines.